Model comparisons - tested September 2026 by Vitus Pruser. How we test.
Verdict
GPT-6 Astra won 9 of 10 prompts blind and finished all ten with zero hallucinations. DeepSeek V4 Pro cost half as much, won the bill split and matched GPT-6 Astra on every data calculation, but dropped facts in the rewrite, gave one wrong population figure and never finished the JavaScript fix inside the Arena time limit. Use DeepSeek V4 Pro for high volume calculation and drafting, GPT-6 Astra when the answer has to be right the first time.
Verdict by task
| Task | Winner | Why |
|---|
| Writing | GPT-6 Astra | DeepSeek wrote a solid customer email but its rewrite dropped two of the facts the prompt said to keep, which is a partial. |
| Coding | GPT-6 Astra | DeepSeek passed slugify with a hard coded letter table that misses characters like c cedilla, and did not finish the off by one cent fix within the Arena time limit in two attempts. |
| Research | GPT-6 Astra | GPT-6 Astra was fully correct and sourced on both. DeepSeek omitted the 85,000 EUR national VAT cap and stated Indonesia at 280 million against the UN figure of about 283.5 million. |
| Data analysis | GPT-6 Astra | Every number was correct from both models; the panel preferred GPT-6 Astra's presentation. DeepSeek delivered the same results at about a third of the cost. |
| Reasoning | Split | Both solved both puzzles. DeepSeek won the bill split with a clean table, GPT-6 Astra the water jug puzzle with the most concise correct answer. |
Results, prompt by prompt
writing - winner: GPT-6 Astra
Prompt: Write a 120 word product update email to existing customers of a small accounting software company announcing that bank feeds now sync every hour instead of once a day. Plain, friendly, no exclamation marks, end with one clear call to action.
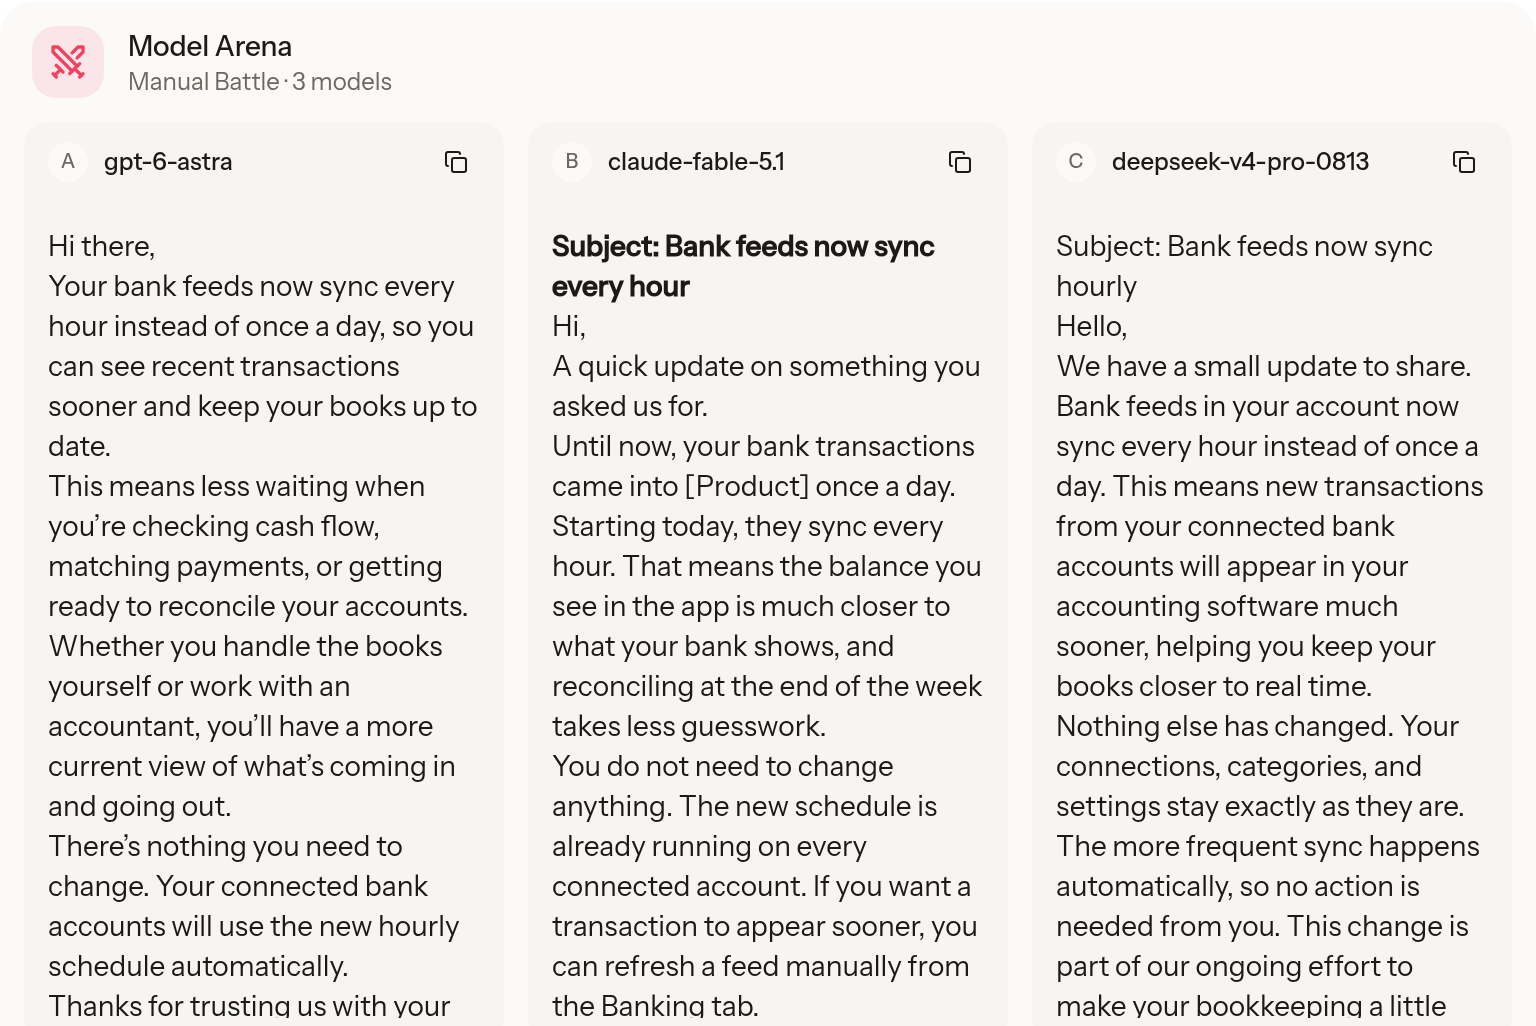
- DeepSeek V4 Pro - pass, no hallucinations, 37.3s. 126 words including subject. Ends with two possible actions (reply or support page, then log in), so the CTA is less singular.
- GPT-6 Astra - pass, no hallucinations, 24.1s. Exactly 120 words, no exclamation marks, one CTA. Plain and friendly as asked.
writing - winner: GPT-6 Astra
Prompt: Rewrite this paragraph so a 12 year old understands it, keep every fact, max 80 words: 'Compound interest is interest calculated on the initial principal and also on the accumulated interest of previous periods. Because the base grows each period, the growth is exponential rather than linear, which is why long time horizons matter far more than the interest rate alone.'
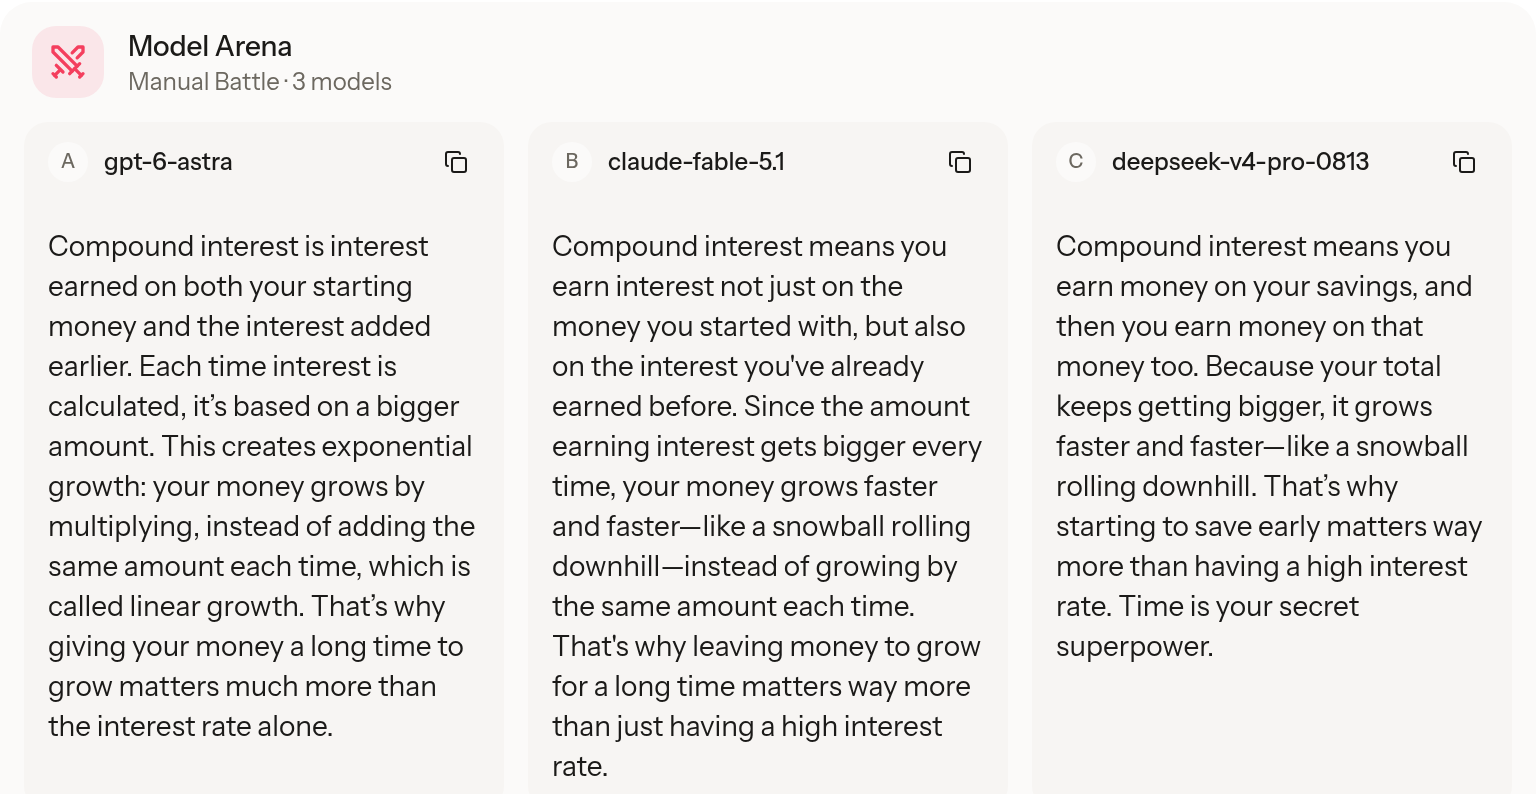
- DeepSeek V4 Pro - partial, no hallucinations, 7.2s. 54 words. Drops the principal plus accumulated interest definition and the exponential versus linear contrast, and rewrites the time horizon fact as starting early. The prompt said keep every fact.
- GPT-6 Astra - pass, no hallucinations, 8.4s. 66 words, keeps all facts including exponential versus linear and the principal plus accumulated interest definition. Reads a bit technical for a 12 year old.
coding - winner: GPT-6 Astra
Prompt: Write a Python function slugify(title: str) -> str that lowercases, replaces any run of non alphanumeric characters with a single hyphen, strips leading and trailing hyphens, and transliterates common accented Latin letters (e, a, o, u with accents, and the German sharp s) to ASCII. Include 5 pytest test cases. No external dependencies.
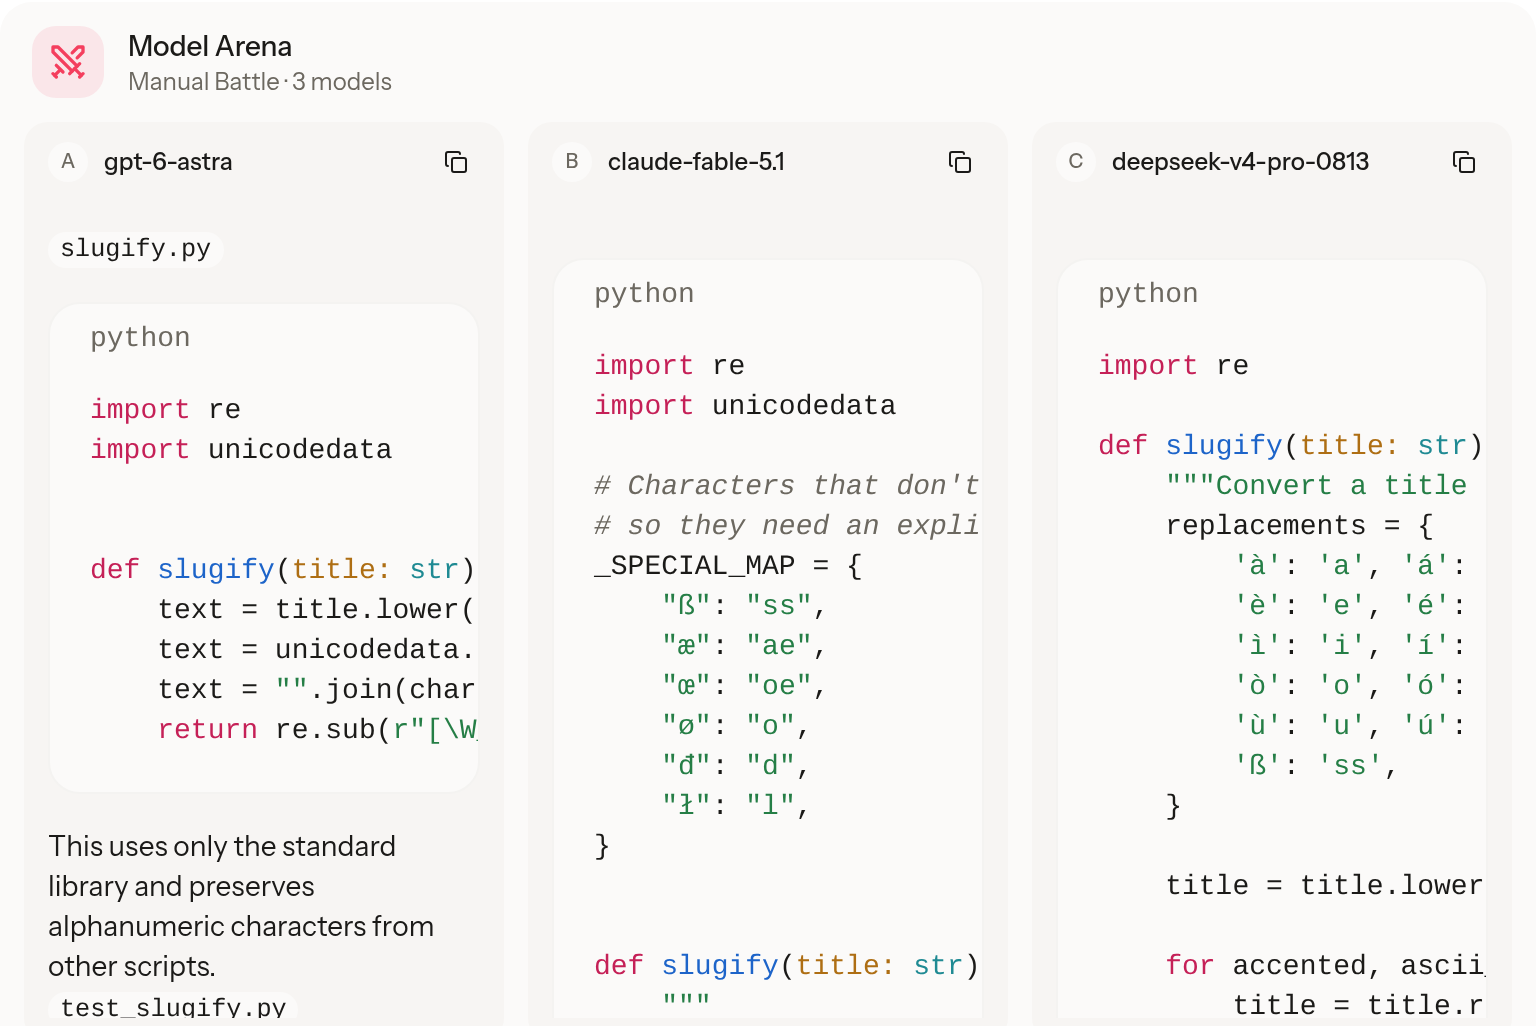
- DeepSeek V4 Pro - pass, no hallucinations, 104.9s. Hard coded replacement table. Own 5 tests pass and it meets the letters named in the prompt, but drops letters outside its table (c cedilla becomes a hyphen, g circumflex disappears). 105 seconds.
- GPT-6 Astra - pass, no hallucinations, 102.5s. Shortest correct solution (unicodedata NFD). Own 5 tests pass, plus 8 of our extra transliteration cases. Slow: 102 seconds, most of it reasoning.
coding - winner: GPT-6 Astra
Prompt: This JavaScript has a bug: users report the total is sometimes off by one cent. Find the bug, explain it in two sentences, and give the corrected function.
function total(items) {
let sum = 0;
for (const it of items) {
sum += it.price * it.qty * (1 + it.taxRate);
}
return Math.round(sum * 100) / 100;
}
- DeepSeek V4 Pro - fail, no hallucinations. Did not finish inside the Arena in two attempts (the model spent about 14,700 reasoning tokens; a direct API call took 197 seconds). No answer to score.
- GPT-6 Astra - pass, no hallucinations, 14.5s. Correctly identifies binary floating point rounding (1.005 * 100 = 100.49999999999999). Fix pulls in decimal.js, a dependency the prompt did not ask for.
research - winner: GPT-6 Astra
Prompt: What is the current EU VAT registration threshold for small businesses under the EU wide SME scheme that started in 2025, in euros, and which regulation introduced it? Answer in 3 sentences and say if you are unsure about any figure.
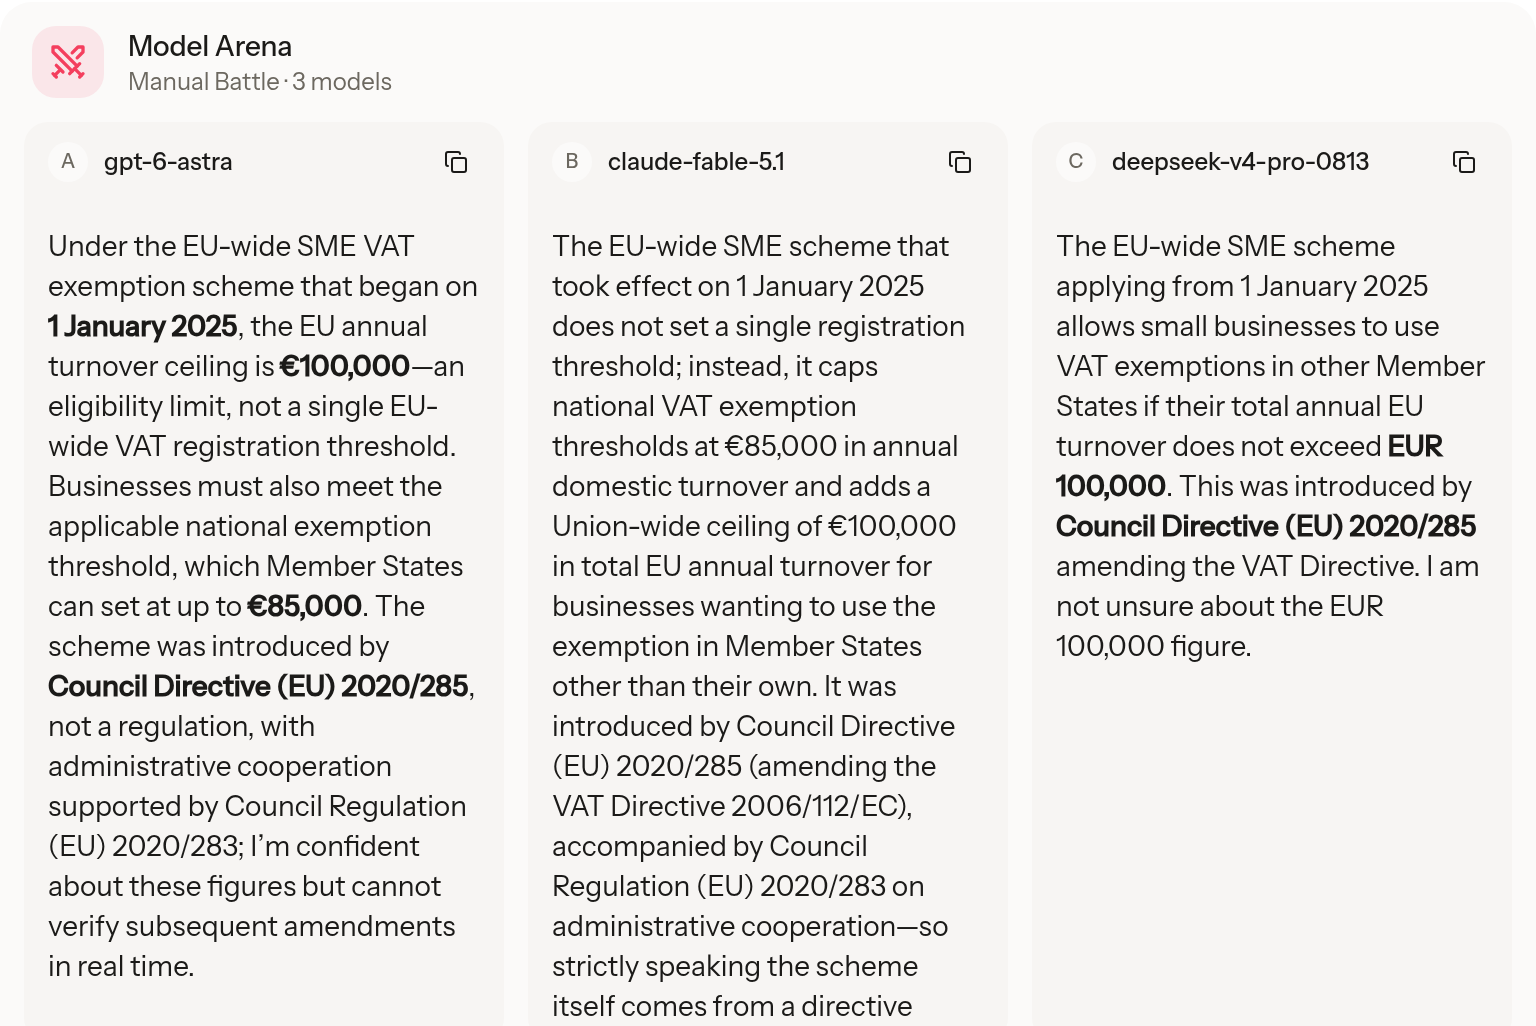
- DeepSeek V4 Pro - partial, no hallucinations, 18.2s. 100,000 EUR and Directive 2020/285 are correct, but it omits the 85,000 EUR national cap, the piece a small business actually registers against, and the closing sentence about uncertainty is awkwardly phrased.
- GPT-6 Astra - pass, no hallucinations, 13.3s. Correct: 100,000 EUR Union threshold, 85,000 EUR national cap, Council Directive (EU) 2020/285 and Regulation 2020/283, 1 January 2025. Flags that it is a directive, not a regulation. Checked against the directive text.
research - winner: GPT-6 Astra
Prompt: List the 5 largest countries by population in 2024 with their approximate population, and name the source you would cite for these figures. Table format.
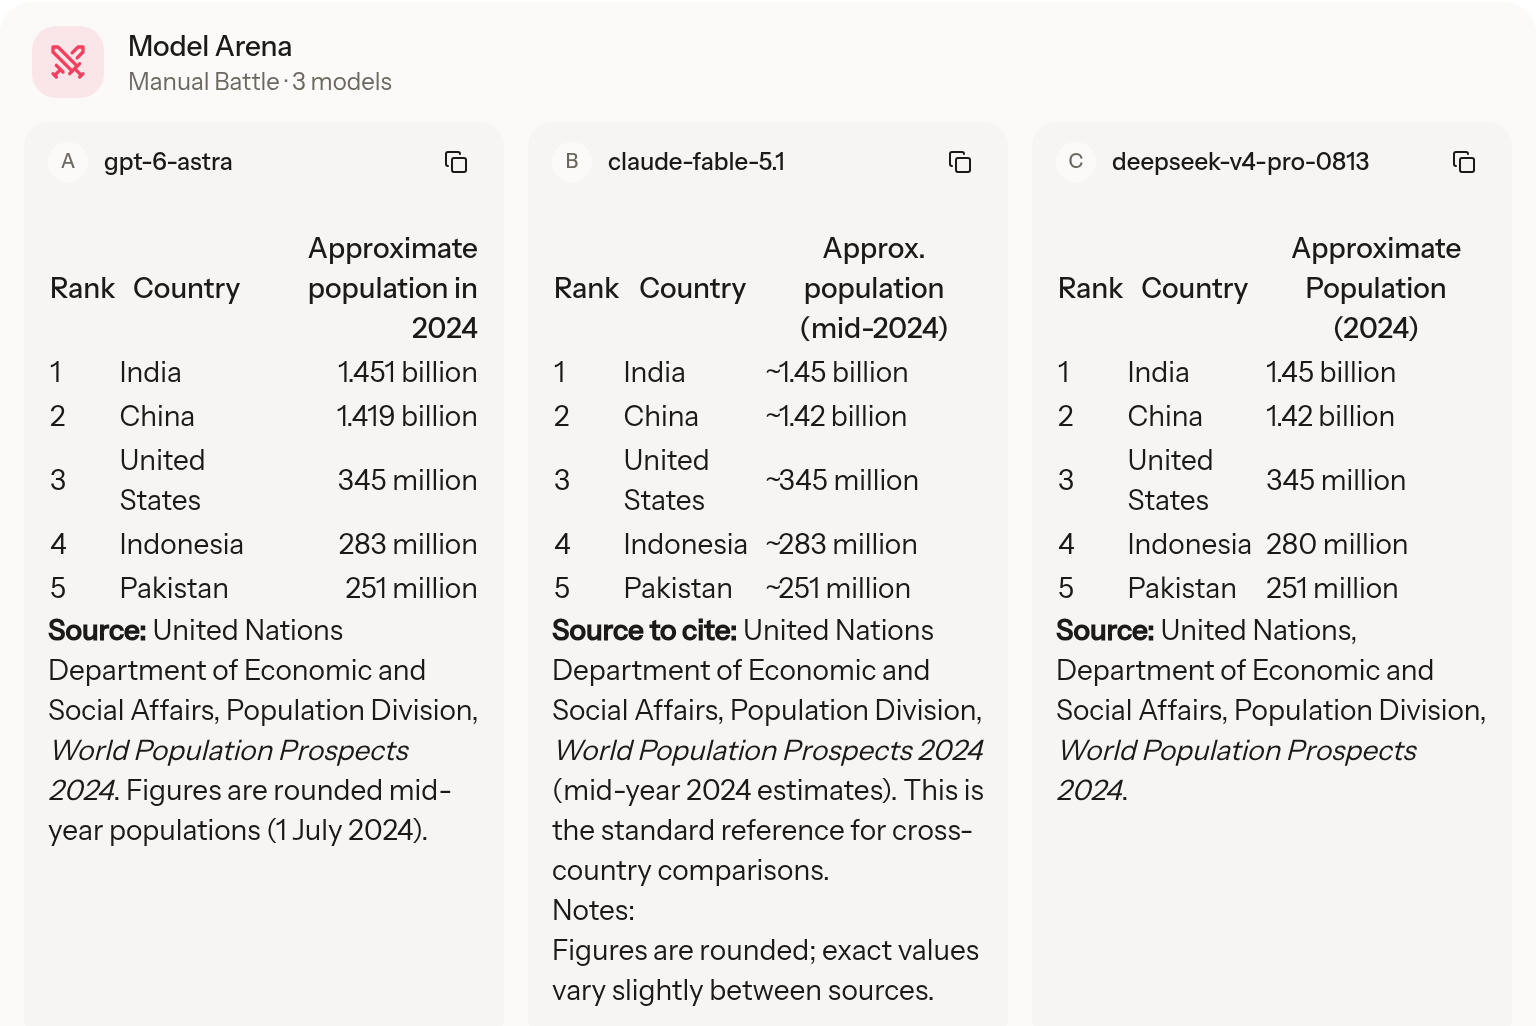
- DeepSeek V4 Pro - pass, 1 hallucination, 16s. Ranking correct, source correct. Indonesia given as 280 million; the UN 2024 estimate is about 283.5 million, and the 2023 figure was already 281.2 million. Counted as one factual inaccuracy.
- GPT-6 Astra - pass, no hallucinations, 12.4s. Ranking and figures match UN World Population Prospects 2024 mid-2024 estimates, source named with link.
data - winner: GPT-6 Astra
Prompt: Here are monthly revenue figures in EUR for a shop: Jan 41200, Feb 38900, Mar 45100, Apr 47800, May 46200, Jun 52300, Jul 55900, Aug 51400, Sep 58700. Compute the month over month growth for each month, the average growth rate, and the best and worst month. Show the numbers in a table and state the totals.
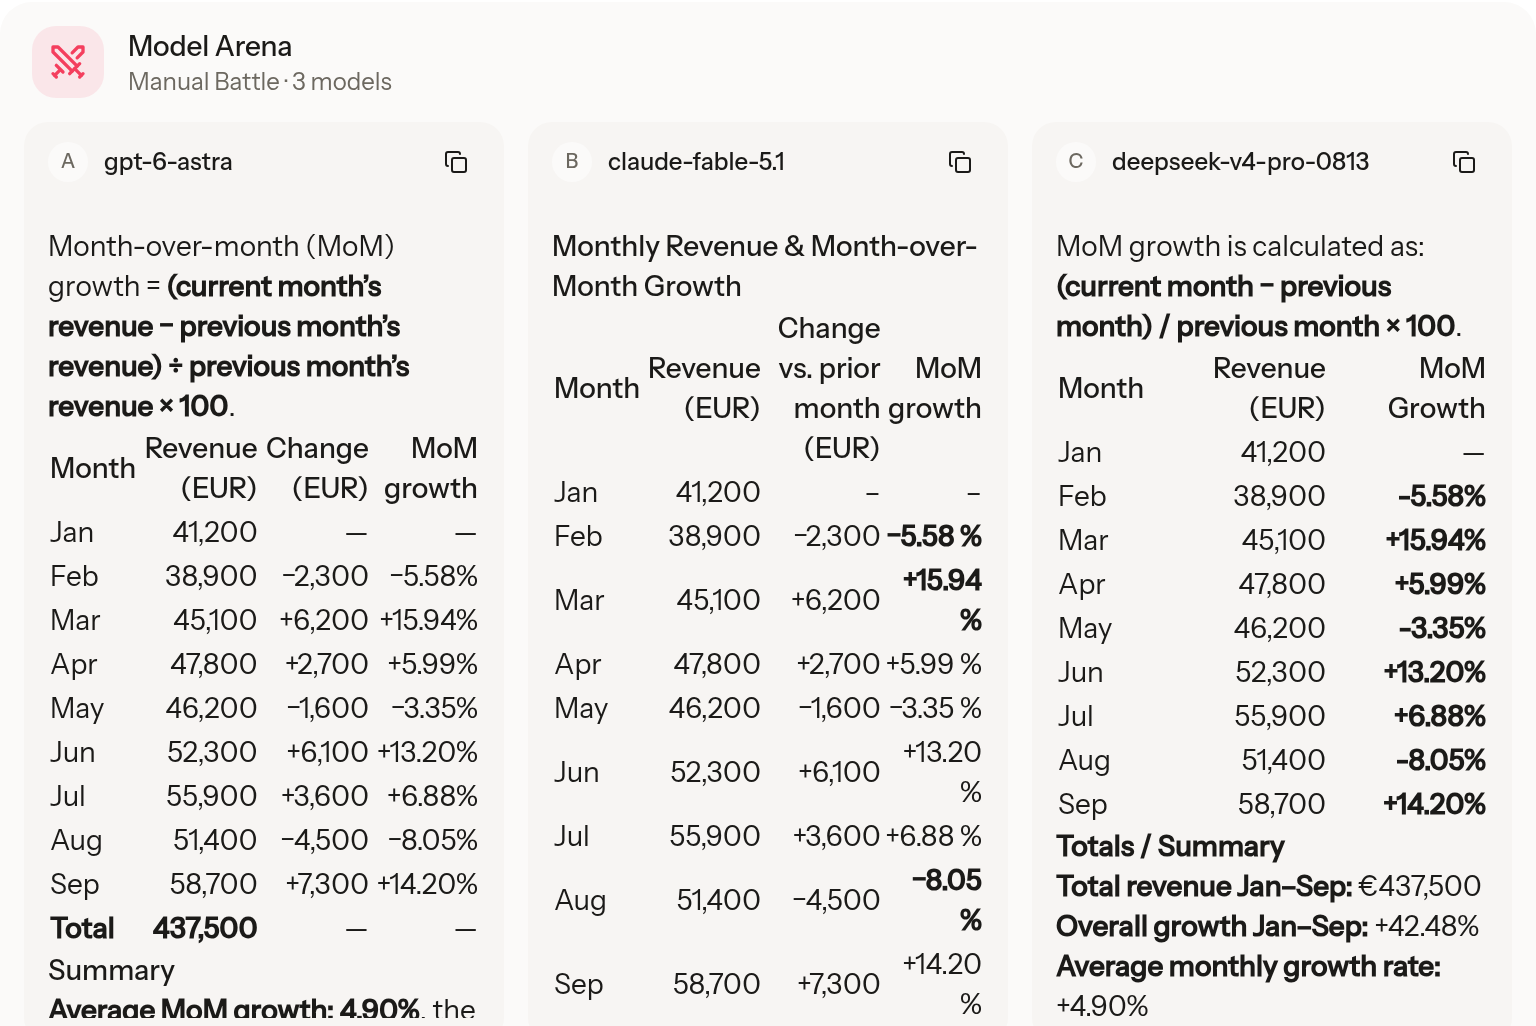
- DeepSeek V4 Pro - pass, no hallucinations, 108.4s. All numbers verified correct including the 4.52 percent compound rate. Leanest table. 108 seconds.
- GPT-6 Astra - pass, no hallucinations, 101.2s. All eight growth rates, 4.90 percent average, 437,500 total, best and worst by revenue and by growth all verified correct. 101 seconds.
data - winner: GPT-6 Astra
Prompt: A SaaS company has 1,240 customers paying an average of 49 EUR per month and loses 3.1 percent of customers each month. New signups are 85 per month. Estimate the customer count and MRR after 12 months assuming these rates hold. Show your working and round to whole numbers.
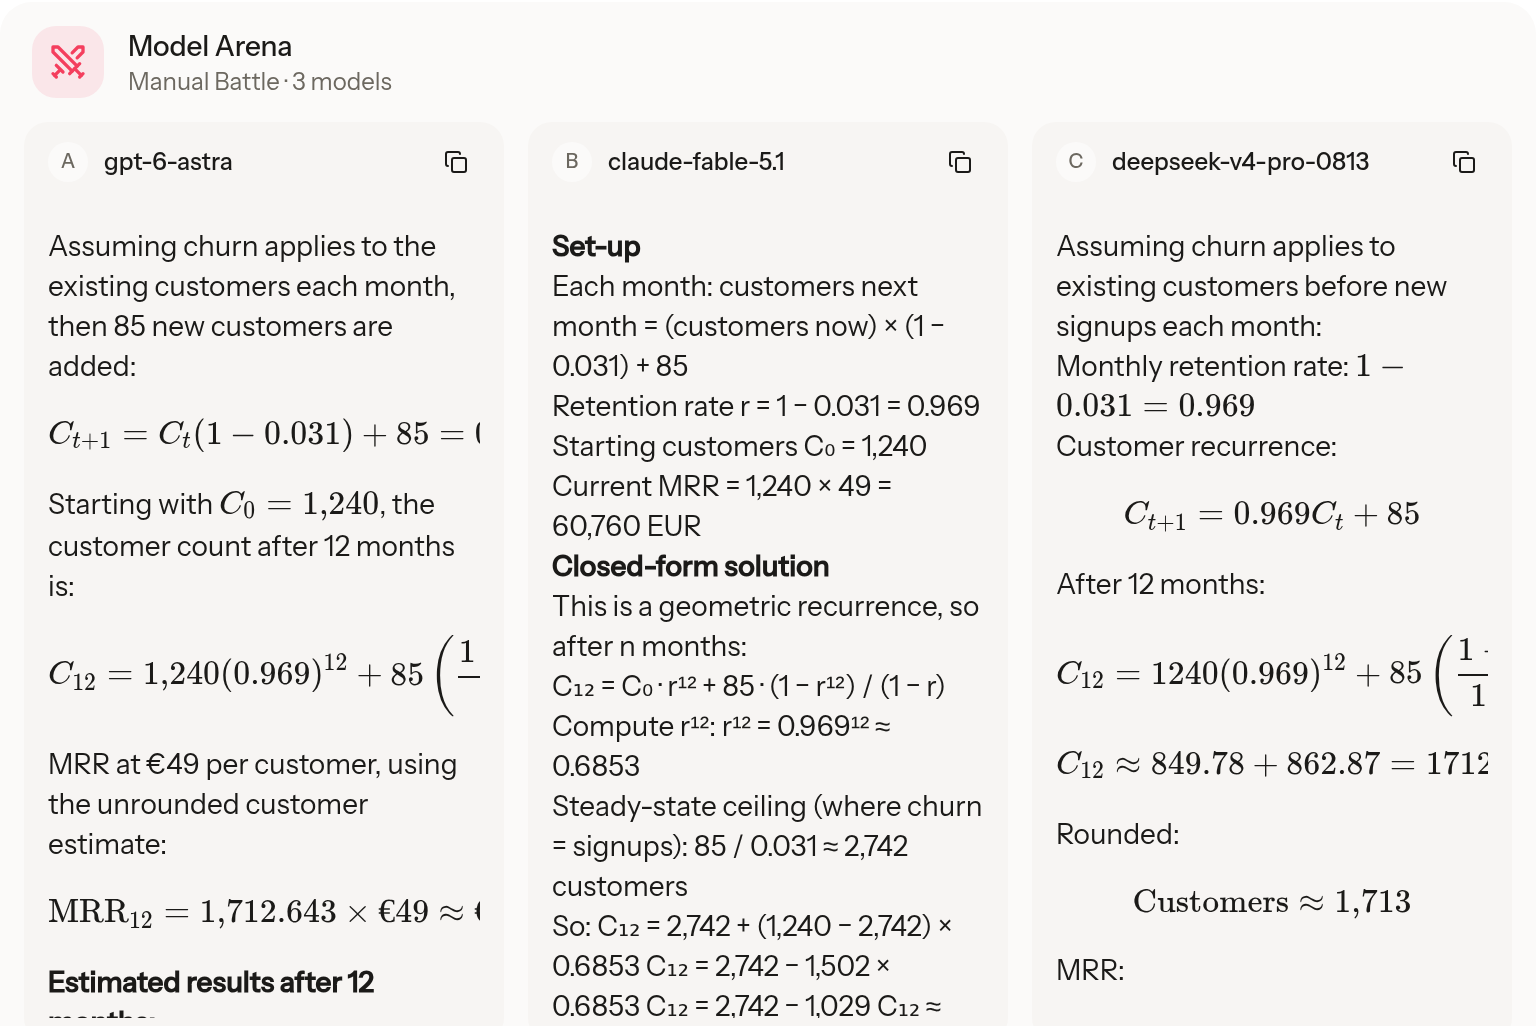
- DeepSeek V4 Pro - pass, no hallucinations, 43.4s. Same closed form, correct, and it points out the 83,920 versus 83,937 rounding difference explicitly.
- GPT-6 Astra - pass, no hallucinations, 42.2s. Closed form recurrence, 1,713 customers and 83,920 EUR MRR, verified (1,712.65 and 83,919.76). Uses LaTeX, which the Arena renders.
reasoning - winner: GPT-6 Astra
Prompt: I have a 3 litre jug and a 5 litre jug and unlimited water. Give the shortest sequence of steps to measure exactly 4 litres. Then say how many steps it took.
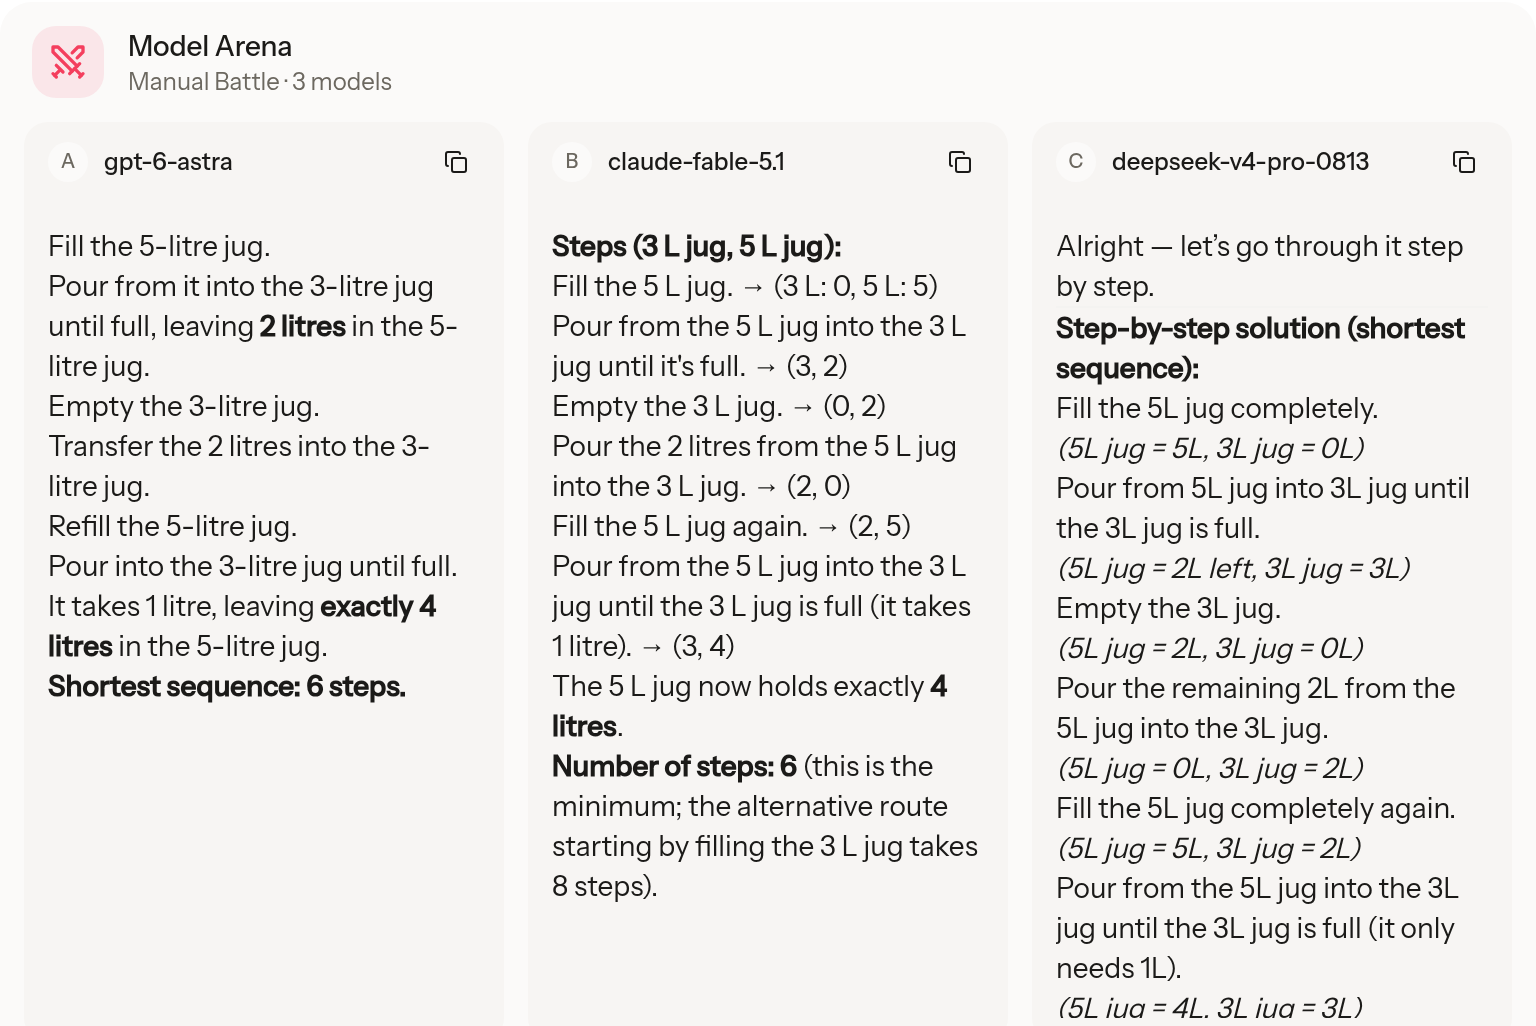
- DeepSeek V4 Pro - pass, no hallucinations, 15.6s. Correct 6 steps with states. Opens with filler and closes with an offer to continue, which the prompt did not ask for.
- GPT-6 Astra - pass, no hallucinations, 10.8s. Correct 6 step sequence, correct count. Most concise.
reasoning - winner: DeepSeek V4 Pro
Prompt: Three colleagues need to split a 187 EUR dinner. Anna had no drinks and her food was 41 EUR. Ben and Clara shared two bottles of wine totalling 58 EUR and their food was 44 EUR each. Who owes what, so that everyone pays exactly for what they consumed? Show the check that the parts add up to 187.
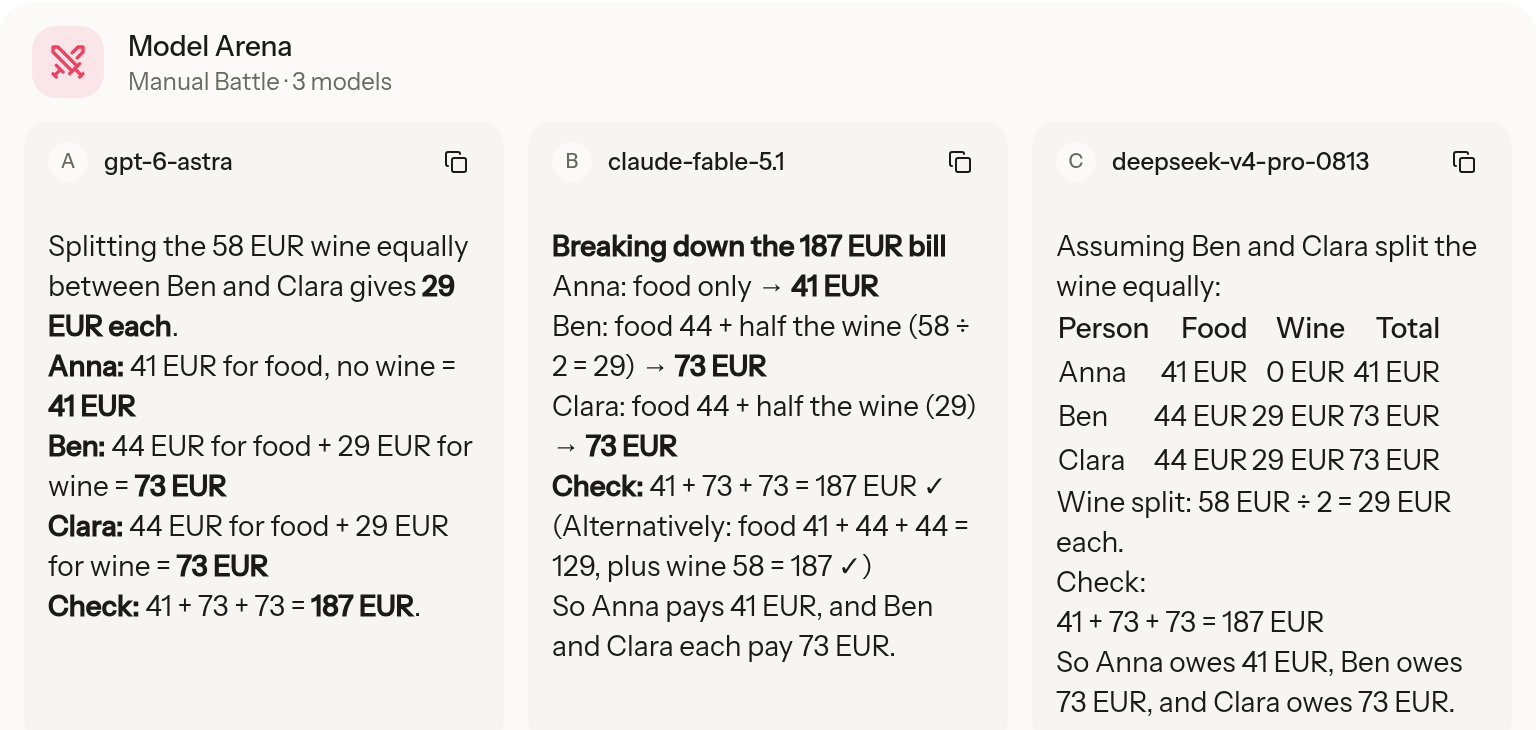
- DeepSeek V4 Pro - pass, no hallucinations, 10.8s. Correct, table format, states the equal wine split assumption.
- GPT-6 Astra - pass, no hallucinations, 7.2s. 41, 73, 73, check to 187. Correct and shortest.
Frequently asked questions
Is DeepSeek as good as ChatGPT?
Not across the board in our September 2026 round. GPT-6 Astra won 9 of 10 prompts in a blind review with zero hallucinations. DeepSeek V4 Pro matched it on every calculation and won the bill split puzzle, but produced two partials, one factual slip and one unfinished task.
Is DeepSeek cheaper than ChatGPT?
Yes. Measured in Krater, the ten DeepSeek V4 Pro answers cost $0.11 in total against $0.23 for GPT-6 Astra, and on short prompts DeepSeek was often ten times cheaper. On the coding prompts the gap closed because DeepSeek spent heavily on reasoning tokens.
Why did DeepSeek fail the JavaScript task?
DeepSeek V4 Pro reasoned for about 14,700 tokens on the off by one cent bug and did not return an answer within the Arena's time limit in two attempts. A direct API call finished after 197 seconds. We score what the model delivered under the same conditions as the others, so it counts as a fail.
Can I use DeepSeek and ChatGPT in the same place?
Yes. Krater gives you DeepSeek V4 Pro, GPT-6 Astra and 500+ other models in one workspace, and the Model Arena lets you send one prompt to several models side by side, which is how this comparison was run.
How was this comparison tested?
All three models (GPT-6 Astra, Claude Fable 5.1 and DeepSeek V4 Pro) received the same ten prompts side by side in the Krater Model Arena on 16 September 2026, with default settings and no system prompt. We recorded time to a complete answer and the model cost per answer, fact checked every claim against a primary source, scored task completion as pass, partial or fail, and then Malte and Vitus Pruser ranked the answers blind, without knowing which model wrote which. The full procedure is on our methodology page.
Will this comparison be updated?
Yes. Flagship comparisons are rerun monthly and whenever a provider ships a new version. The tested month and model versions are shown at the top of the page.

