Model comparisons - tested October 2026 by Vitus Pruser. How we test.
Verdict
Claude Fable 5.1 took 9 of 10 prompts; the quality gap between these two is the largest of any pair we tested this round. Claude wrote better copy, code that passes all its own tests with documentation, and data answers with real insight. Grok 4.3's one win is the water jug on brevity, but its real argument is economics: the whole ten-prompt round cost $0.02 versus Claude's $0.42, and it answered faster. Use Grok for volume and drafts; use Claude when the answer has to be right.
Verdict by task
| Task | Winner | Why |
|---|
| Writing | Claude Fable 5.1 | Claude wrote the only full email with subject and signoff and the most readable rewrite; Grok was functional but flat and dropped a key contrast. |
| Coding | Claude Fable 5.1 | Claude passed all its tests with the best documentation; Grok failed one of its own slugify tests and silently changed rounding semantics in the fix. |
| Research | Claude Fable 5.1 | Claude gave complete figures plus the accompanying regulation and source guidance; Grok was correct but thinner and cited Worldometer over the UN. |
| Data analysis | Claude Fable 5.1 | Both computed correctly, but Claude added compound growth, the trend read and the steady-state ceiling; Grok gave bare numbers. |
| Reasoning | Split | Both solved both puzzles. Grok won the water jug for the tersest correct answer; Claude won the bill split with the double-checked method. |
Results, prompt by prompt
writing - winner: Claude Fable 5.1
Prompt: Write a 120 word product update email to existing customers of a small accounting software company announcing that bank feeds now sync every hour instead of once a day. Plain, friendly, no exclamation marks, end with one clear call to action.
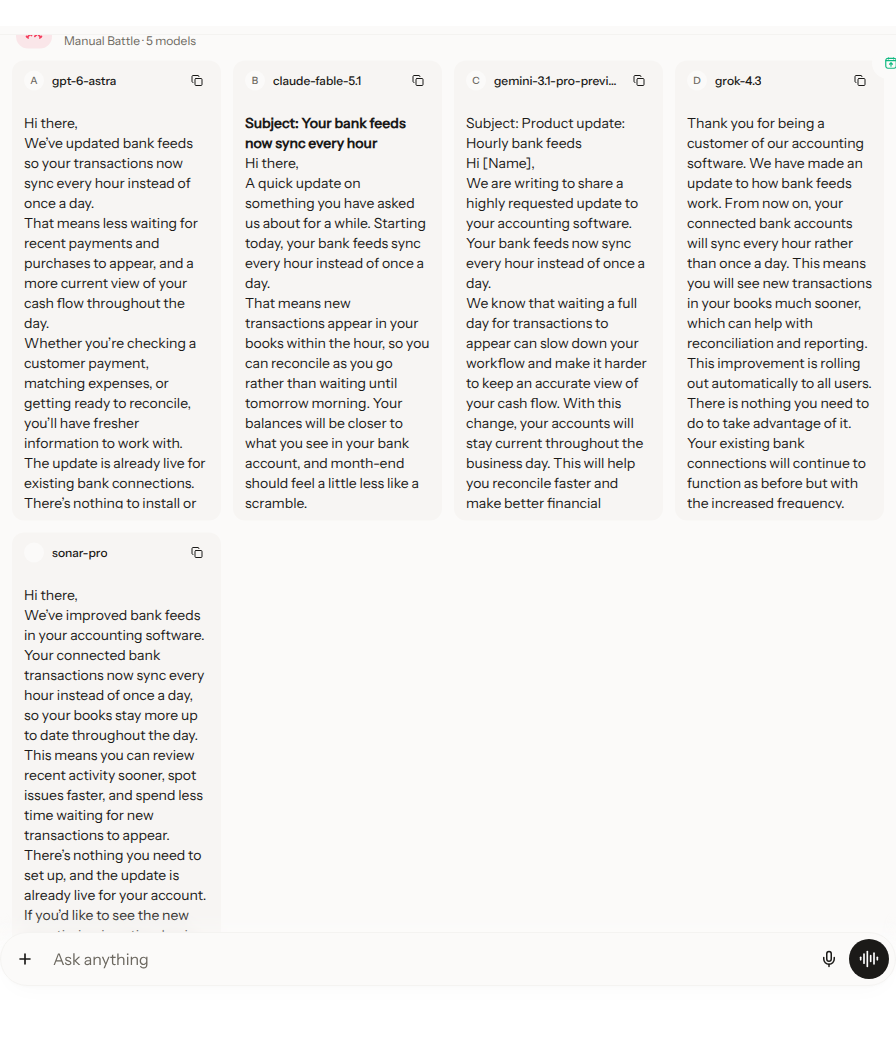
- Grok 4.3 - pass, no hallucinations, 16.1s. 103 words, functional but flat: a "Thank you for being a customer" opener and the weakest flow.
- Claude Fable 5.1 - pass, no hallucinations, 33.5s. 131 words, about 9% over target, but the most complete email: subject line, signoff and a support line. Best copy.
writing - winner: Claude Fable 5.1
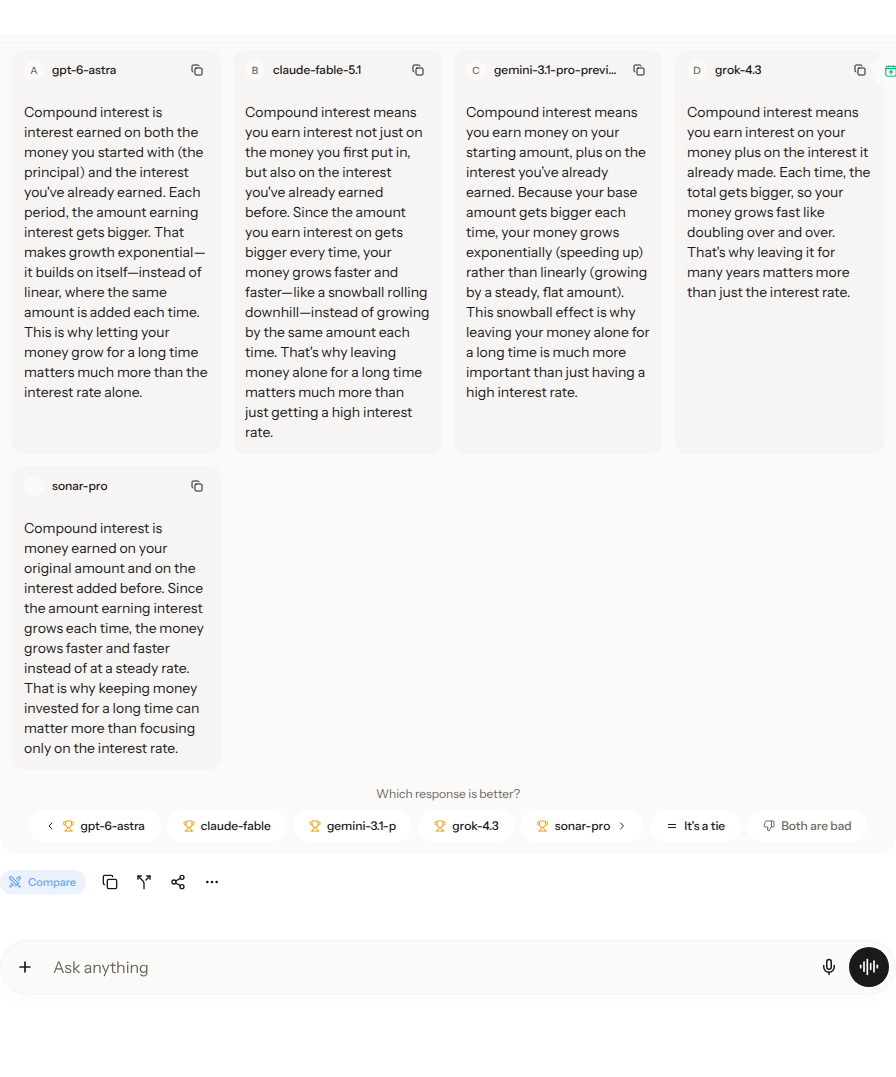
Prompt: Rewrite this paragraph so a 12 year old understands it, keep every fact, max 80 words: 'Compound interest is interest calculated on the initial principal and also on the accumulated interest of previous periods. Because the base grows each period, the growth is exponential rather than linear, which is why long time horizons matter far more than the interest rate alone.'
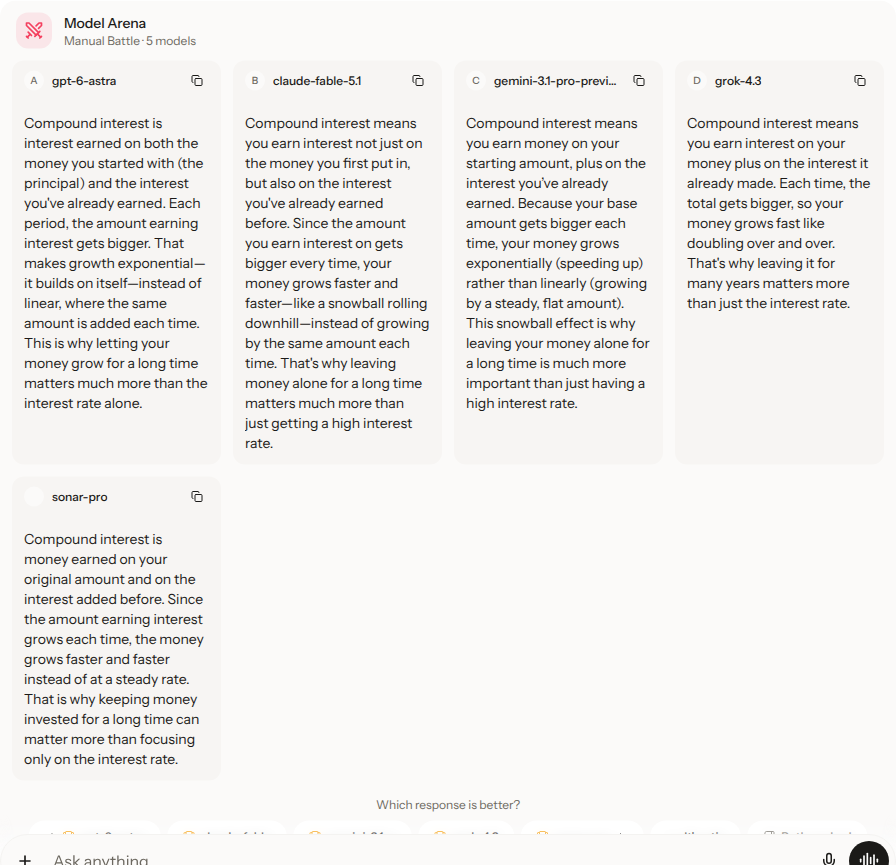
- Grok 4.3 - pass, no hallucinations, 11.3s. 46 words and loses the exponential-versus-linear contrast; "grows fast like doubling" is looser.
- Claude Fable 5.1 - pass, no hallucinations, 11.3s. 74 words, snowball image, keeps every fact. Friendliest read for a 12 year old.
coding - winner: Claude Fable 5.1
Prompt: Write a Python function slugify(title: str) -> str that lowercases, replaces any run of non alphanumeric characters with a single hyphen, strips leading and trailing hyphens, and transliterates common accented Latin letters (e, a, o, u with accents, and the German sharp s) to ASCII. Include 5 pytest test cases. No external dependencies.
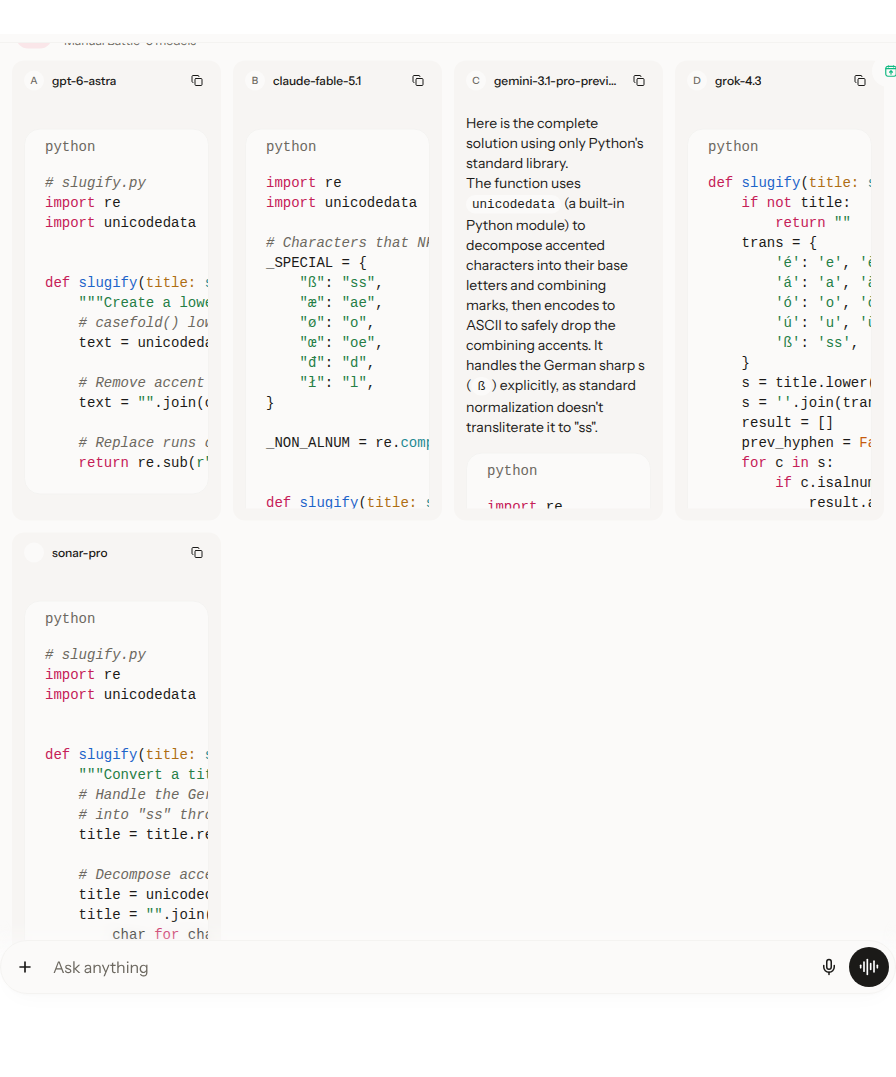
- Grok 4.3 - partial, no hallucinations, 15s. 4 of its own 5 tests pass: its transliteration map misses ï, so its own naïve test case fails.
- Claude Fable 5.1 - pass, no hallucinations, 19s. All 5 tests pass. Best documented approach, with an explicit map for ß, æ, ø and a note on why.
coding - winner: Claude Fable 5.1
Prompt: This JavaScript has a bug: users report the total is sometimes off by one cent. Find the bug, explain it in two sentences, and give the corrected function.
function total(items) {
let sum = 0;
for (const it of items) {
sum += it.price * it.qty * (1 + it.taxRate);
}
return Math.round(sum * 100) / 100;
}
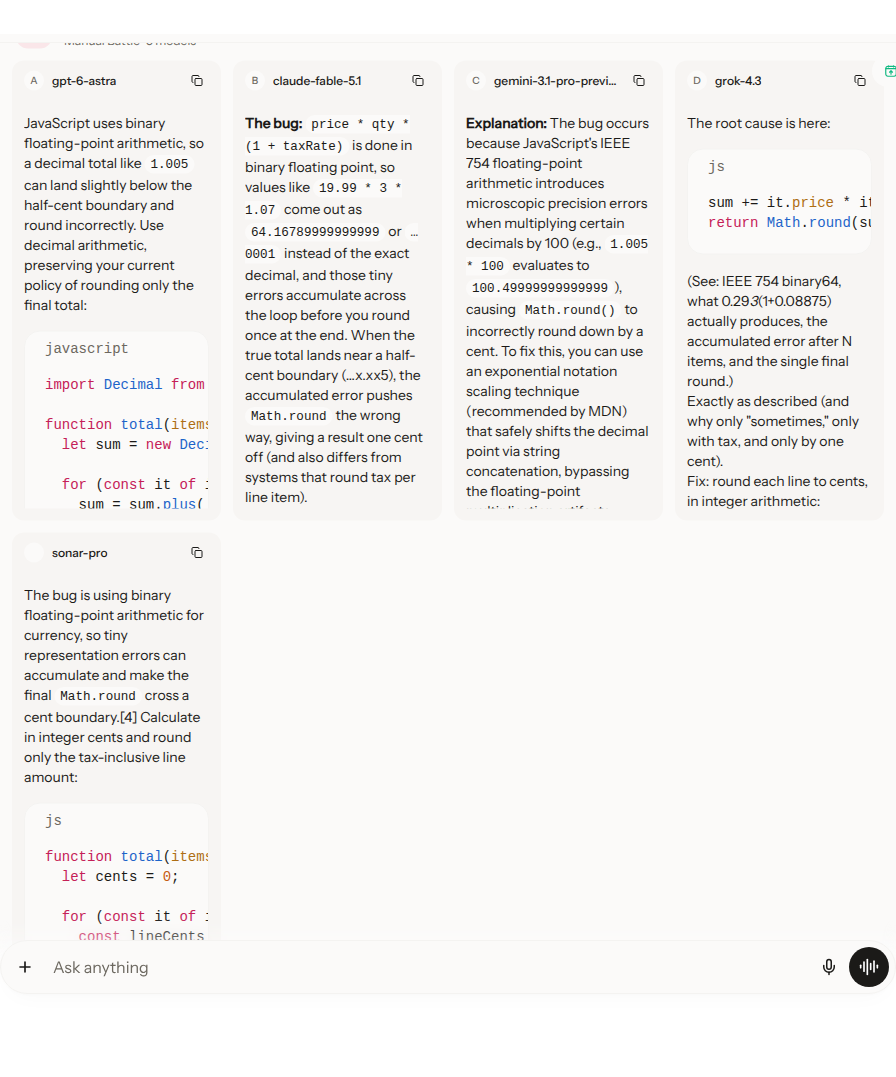
- Grok 4.3 - partial, no hallucinations, 14.6s. Per-line integer cents fixes accumulation, but silently changes the rounding policy and still misses the 4.01 boundary case.
- Claude Fable 5.1 - pass, no hallucinations, 99.1s. Correct diagnosis plus a working integer-cents fix, and it explicitly documents the per-line rounding trade-off. Slowest at 99s.
research - winner: Claude Fable 5.1
Prompt: What is the current EU VAT registration threshold for small businesses under the EU wide SME scheme that started in 2025, in euros, and which regulation introduced it? Answer in 3 sentences and say if you are unsure about any figure.
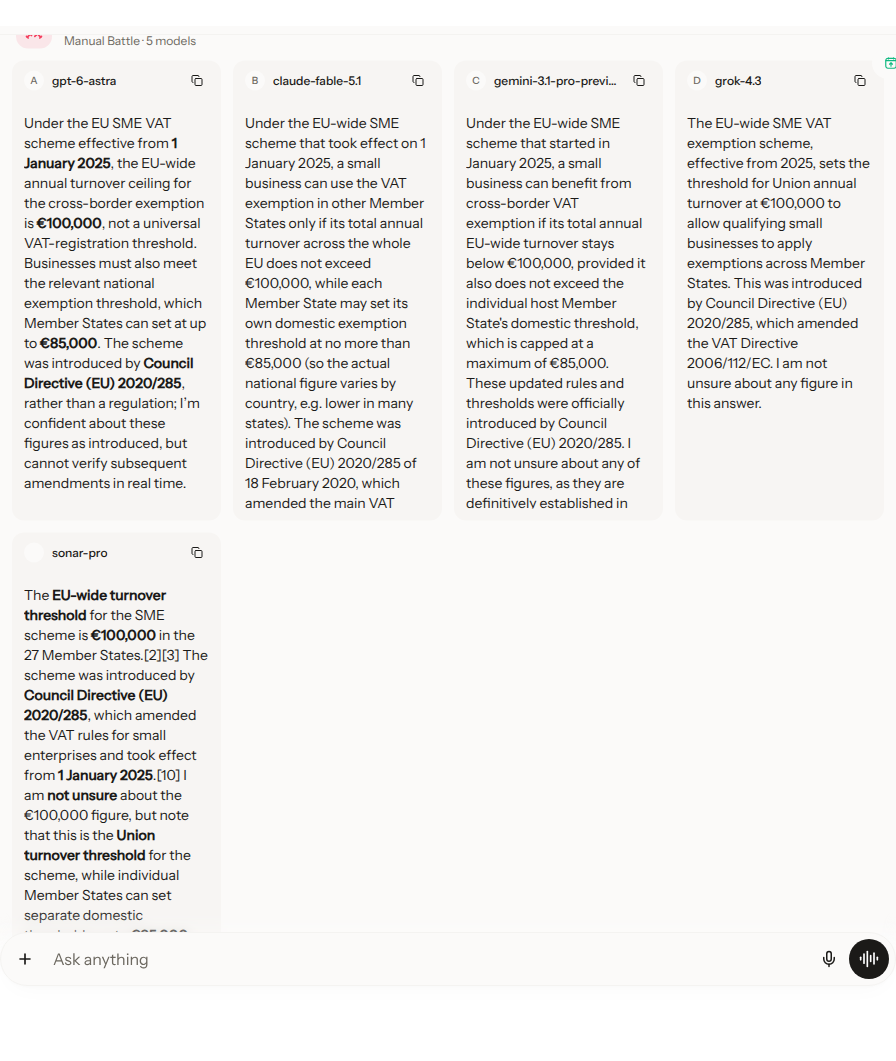
- Grok 4.3 - pass, no hallucinations, 9.8s. Correct on €100,000 and Directive 2020/285, but omits the €85,000 national cap the question asked about.
- Claude Fable 5.1 - pass, no hallucinations, 12.2s. Correct figures, names the accompanying Regulation 2020/283, and notes national thresholds vary. Most complete.
research - winner: Claude Fable 5.1
Prompt: List the 5 largest countries by population in 2024 with their approximate population, and name the source you would cite for these figures. Table format.
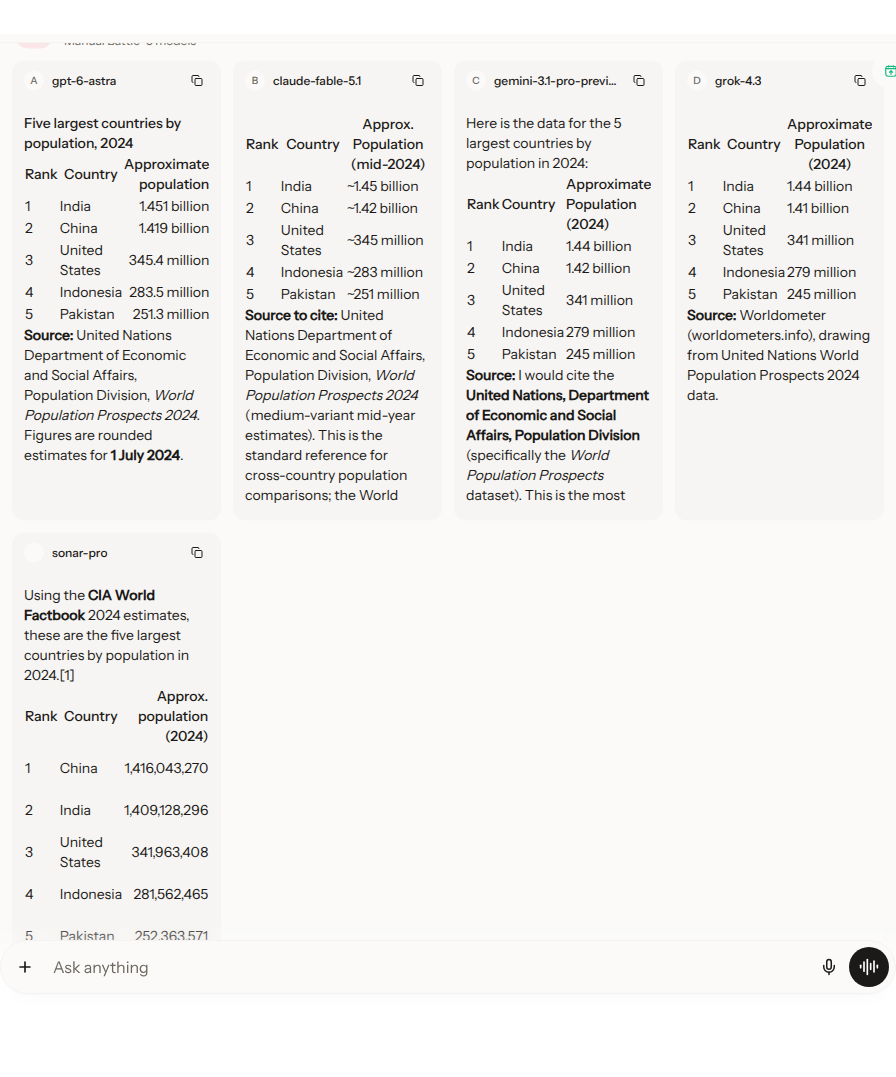
- Grok 4.3 - pass, no hallucinations, 9.8s. Right ranking, but cites Worldometer instead of the UN primary source; figures ~4 to 6m low.
- Claude Fable 5.1 - pass, no hallucinations, 11s. Correct UN figures (~1.45b India) and the best source guidance: UN WPP plus named alternatives.
data - winner: Claude Fable 5.1
Prompt: Here are monthly revenue figures in EUR for a shop: Jan 41200, Feb 38900, Mar 45100, Apr 47800, May 46200, Jun 52300, Jul 55900, Aug 51400, Sep 58700. Compute the month over month growth for each month, the average growth rate, and the best and worst month. Show the numbers in a table and state the totals.
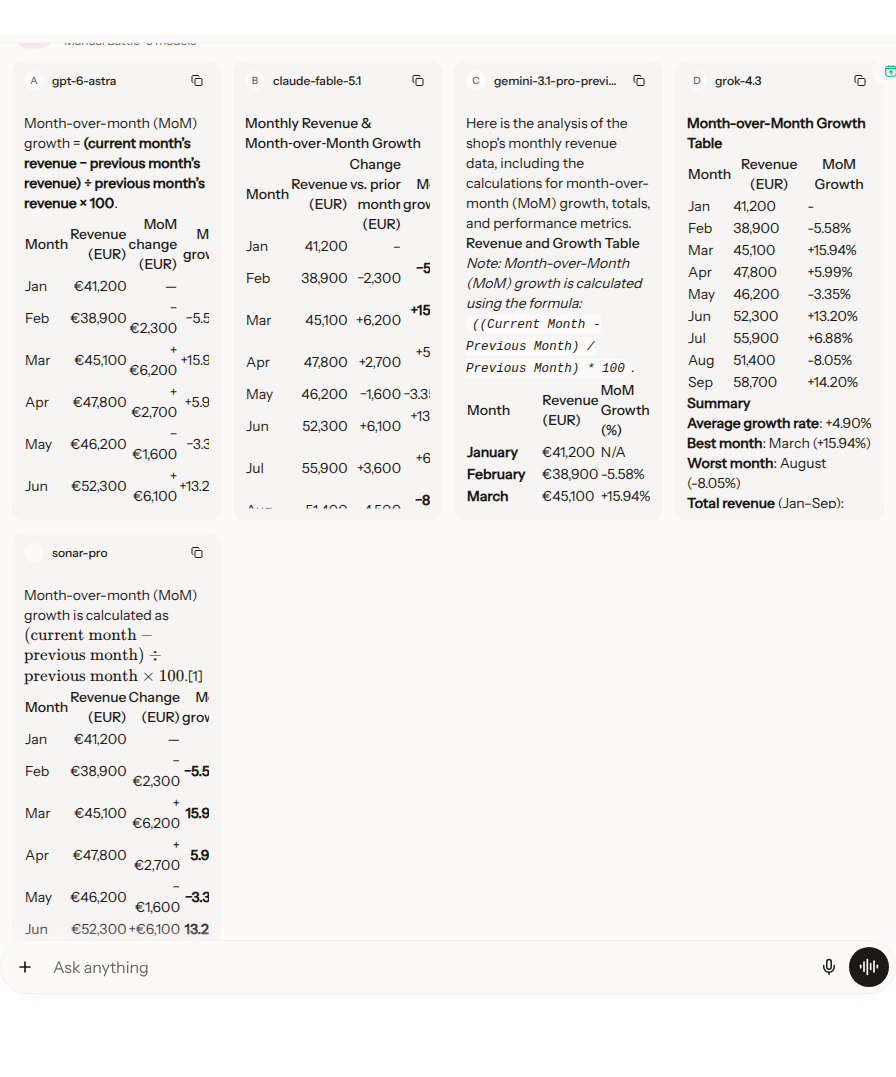
- Grok 4.3 - pass, no hallucinations, 13.4s. Every number correct, bare-minimum presentation.
- Claude Fable 5.1 - pass, no hallucinations, 22.1s. All figures correct plus average revenue, compound monthly growth and the sawtooth trend call. Thorough.
data - winner: Claude Fable 5.1
Prompt: A SaaS company has 1,240 customers paying an average of 49 EUR per month and loses 3.1 percent of customers each month. New signups are 85 per month. Estimate the customer count and MRR after 12 months assuming these rates hold. Show your working and round to whole numbers.
- Grok 4.3 - pass, no hallucinations, 18.2s. Correct 1,713 and 83,937, self-verifies by iteration. Concise.
- Claude Fable 5.1 - pass, no hallucinations, 25.3s. 1,713 customers and 83,937 EUR, plus a month-by-month table and the 2,742 steady-state ceiling insight.
reasoning - winner: Grok 4.3
Prompt: I have a 3 litre jug and a 5 litre jug and unlimited water. Give the shortest sequence of steps to measure exactly 4 litres. Then say how many steps it took.
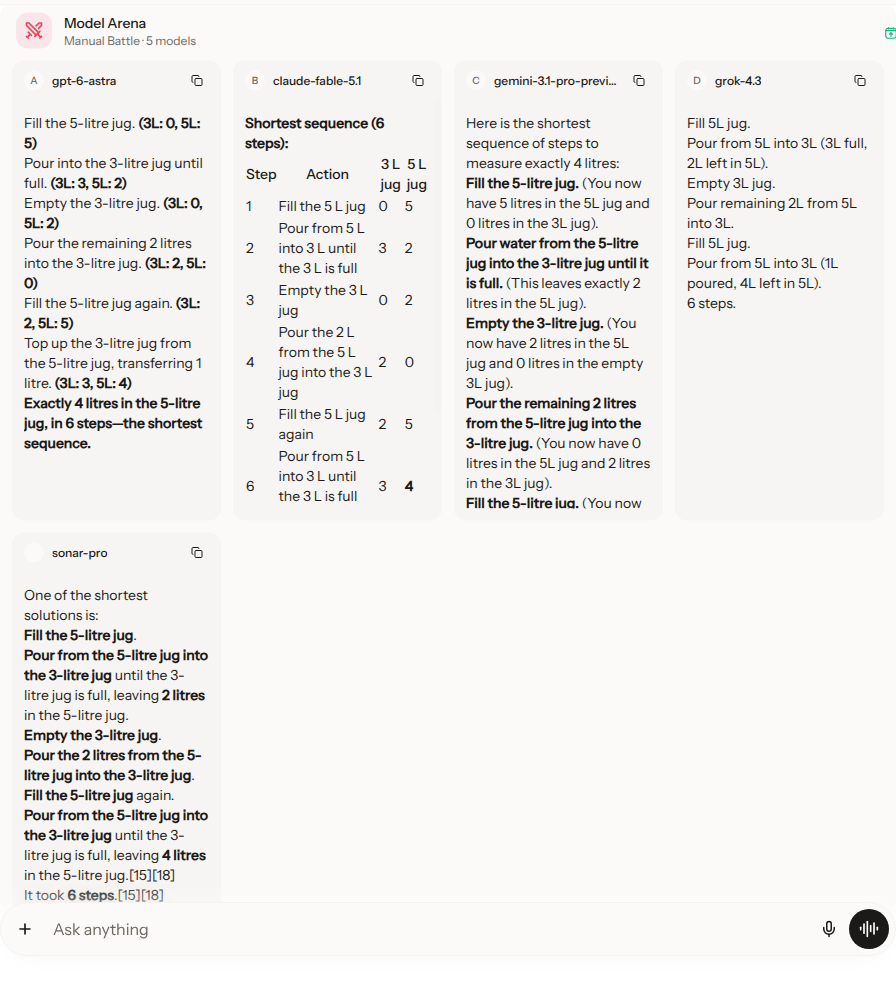
- Grok 4.3 - pass, no hallucinations, 8.7s. Optimal 6 steps and the tersest answer of the five: exactly what the prompt asked.
- Claude Fable 5.1 - pass, no hallucinations, 13.4s. Optimal 6 steps and proves it: the alternative route needs 8.
reasoning - winner: Claude Fable 5.1
Prompt: Three colleagues need to split a 187 EUR dinner. Anna had no drinks and her food was 41 EUR. Ben and Clara shared two bottles of wine totalling 58 EUR and their food was 44 EUR each. Who owes what, so that everyone pays exactly for what they consumed? Show the check that the parts add up to 187.
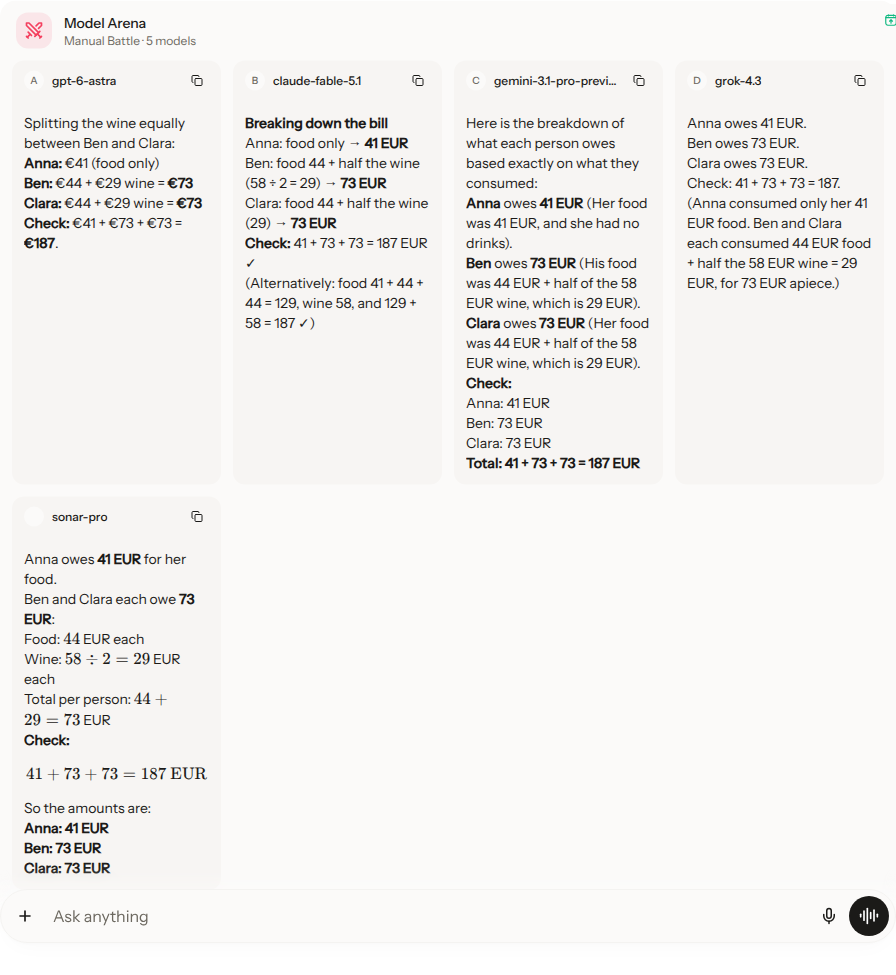
- Grok 4.3 - pass, no hallucinations, 8.6s. 41, 73, 73, correct, with a short method note.
- Claude Fable 5.1 - pass, no hallucinations, 8.6s. 41, 73, 73, plus a second verification (food 129 + wine 58).
Frequently asked questions
Is Grok or Claude better?
Claude by a wide margin on quality: it won 9 of 10 blind-ranked prompts in our October 2026 round and was the strongest model in the whole test. Grok 4.3's advantage is price and speed: about a twentieth of the cost per answer and a few seconds faster.
Is Grok or Claude better for coding?
Claude. Its slugify passed all five of its own tests with the clearest documentation, while Grok 4.3 failed one of its own test cases and produced a rounding fix that silently changes the rounding policy.
Which is cheaper, Grok or Claude?
Grok, dramatically: $0.02 total across the ten prompts against $0.42 for Claude Fable 5.1, measured in Krater. Grok is the cheapest flagship we tested.
Can I use Grok and Claude in the same place?
Yes. Krater gives you Grok 4.3, Claude Fable 5.1 and 500+ other models in one workspace, and the Model Arena sends one prompt to several models side by side, which is how this comparison was run.
How was this comparison tested?
All five models (GPT-6 Astra, Claude Fable 5.1, Gemini 3.1 Pro Preview, Grok 4.3 and Perplexity Sonar Pro) received the same ten prompts side by side in the Krater Model Arena on 7 October 2026, with default settings and no system prompt; this page compares the two you are looking at. We recorded time to a complete answer and the real model cost per answer, ran the generated code through its own test suites, fact checked every claim, scored completion as pass, partial or fail, and then ranked the answers blind. The full procedure is on our methodology page.
Will this comparison be updated?
Yes. Flagship comparisons are rerun monthly and whenever a provider ships a new version. The tested month and model versions are shown at the top of the page.

